How I Review Flink SQL Solutions
When working with Apache Flink®’s SQL API, it’s not unusual for several possible solutions to suggest themselves. Some solutions may have unexpected consequences, affecting flexibility, performance, cost, and maintainability.
In this post I’ll share what I’m looking for and thinking about when I review a Flink SQL statement: state, append-only vs. updating streams, late events, latency, and determinism.
The details about the Flink SQL runtime presented here are based on Flink 2.3.0.
Can I avoid unbounded state?
Flink is a distributed framework that supports continuous, non-stop execution of stream processing pipelines. The Flink runtime and its APIs provide developers with the means to perform stateful operations on real-time data streams, while helping them manage the risk that the active state will grow until it has exhausted the underlying storage.
Different SQL operations scale differently as they process more and more records. In general, I always aim to choose operations whose state requirements grow more slowly. For example, consider the difference between these two queries:
- find all orders that were not filled within 48 hours
- find all orders that were never filled
The first query is inherently less expensive, because each order can be removed from consideration whenever (1) it is filled, or (2) after 48 hours, whichever comes first. On the other hand, the second query requires keeping track of every order that has not yet been filled, since the beginning of time.
Looking across the various operations supported by Flink SQL in streaming mode, each of them falls into one of these categories:
- stateless
- constant state
- time-bounded state
- per-key state
- per-record state
In general, time-bounded operations are safe; operations that need per-key state are safe if and only if the keyspace is either fixed or growing slowly; and operations that need to keep track of every record should be avoided whenever possible.
When evaluating potential solutions for your use cases, look for solutions that need less state, or that offer flexibility and control over that state. For example, most Flink SQL operations support a state time-to-live (TTL) configuration setting.
For more details about how much state different SQL operations require, and how to apply state TTL, see the video on using EXPLAIN for troubleshooting from the free Apache Flink SQL course on Confluent Developer.
Can I find a solution that produces an append-only stream?
Event streams come in different flavors:
- append-only (or insert-only) streams: e.g., a stream of clickstream events, where each click is an immutable fact
- updating streams: e.g., a stream of user records, where users come and go and their attributes can be modified
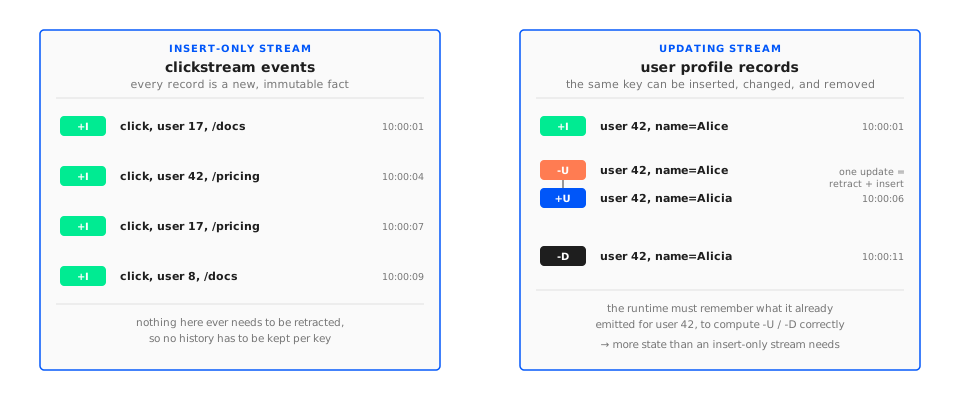
Typically, processing an append-only stream is less expensive. The intuition that explains this is that in many situations, processing an input stream that includes updates and deletions requires maintaining a lot more state. This state is used to remember what has already been emitted, so that the effects of updates and deletions can be computed, and then reflected in the output.
Another reason to prefer append-only streams is that some Flink SQL operations cannot (yet?) be applied to updating streams.
- MATCH_RECOGNIZE
- interval join
- window rank / window deduplicate
- window join
- temporal sort
- ML_PREDICT / VECTOR_SEARCH table functions
- lateral (temporal) snapshot join, on the probe/left side
(The code handling this is in SatisfyModifyKindSetTraitVisitor.)
Of course, for some use cases, a result that includes updates or deletions is the only approach that makes sense. But don’t just blindly accept a solution that produces an updating stream; instead, ask yourself if there might be a better approach.
Once again, Flink’s temporal operations are good choices, because their general behavior is to wait until they have all the information needed to produce a final result, at which point they insert that result into the output stream, and clear the state that had been used to prepare it.
For a more thorough introduction to this topic, see the video on changelog processing and troubleshooting errors about change updates.
Will it be okay if late events are dropped?
In the sections above, I steered you toward Flink’s temporal operations both because they are able to limit how much state they use, and because they produce append-only streams as output. These operations include time-based sorting, windowed aggregations, and interval and temporal joins.
However, there is a potential downside to these temporal operations. In particular, they require that you either
- use processing (or wall clock) time as the basis for timing and ordering, which will make the results troublingly non-deterministic, or
- rely on timestamps in the events as the basis for timing and ordering information, along with watermarks
Because of the drawbacks involved, Confluent Cloud for Apache Flink doesn’t support operations that are based on processing time.
As for relying instead on timestamps carried by the events, the issue is that it isn’t possible to know with certainty when all of the data that would affect a given operation has been ingested. (Or in other words, perfect watermarking isn’t possible.)
For example, consider this example, presented earlier:
find all orders that were not filled within 48 hours
For any given order, how long will you wait for a matching fulfillment event? Well, however long you do wait, eventually you will need to stop waiting and report that order as being unfulfilled.
Now comes the crucial part: suppose that after an order has been deemed unfulfilled within 48 hours, a matching fulfillment event arrives, proving that the order was actually fulfilled on time.
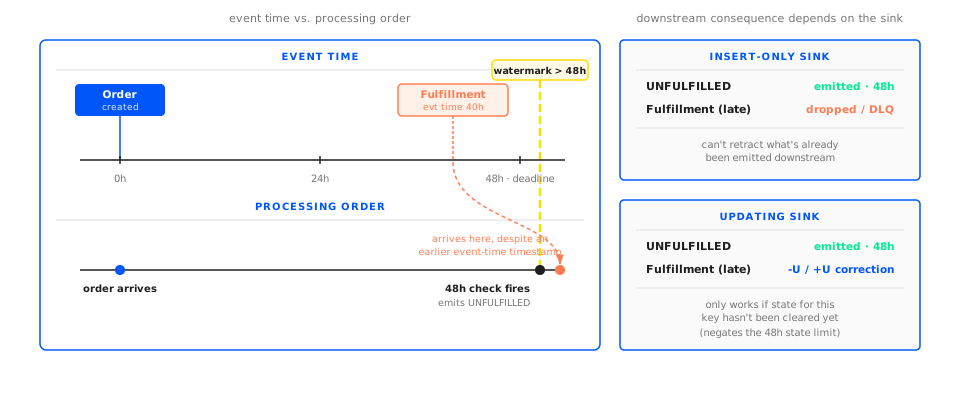
There are only two possibilities for what the Flink runtime might do in this situation:
If this operation has been designed to produce an append-only result stream, and the order has already been emitted downstream, incorrectly classified as unfulfilled, then that result cannot be retracted or updated. Flink can either drop this late fulfillment event, or put it in a dead letter queue (DLQ) for some other process to deal with.
Or, hypothetically, this operation could’ve been implemented with updates and retractions in mind. In which case, the late event could be handled. Except that doing so negates the advantage of applying the 48 hour time limit — namely, being able to clear the state for orders that remain unfulfilled.
The bottom line is this: Flink SQL’s temporal operations are not able to include the impact of late events in their results. (Lateness has a very specific technical meaning, related to watermarks, but think of it as meaning “excessively out-of-order”.)
You have some options:
If reducing the likelihood of incomplete results is good enough for your use case, then configure a custom watermark strategy and monitor the metric(s) related to lateness (for open source Flink, use
numLateRecordsDropped; on Confluent Cloud see the docs).If you must account for every event, then you will want to arrange for late events to be collected in a dead letter queue. In open source Flink this can be done with a statement set:
STATEMENT SET BEGIN
  -- send late events to dead letter queue
  INSERT INTO dlq
    SELECT * FROM input
    WHERE rowtime <= CURRENT_WATERMARK(rowtime);
  -- main query
  INSERT INTO results
    SELECT window_start, window_end, COUNT(*)
    FROM TUMBLE(
      (SELECT * FROM input
        WHERE rowtime > CURRENT_WATERMARK(rowtime)),
      DESCRIPTOR(rowtime),
      INTERVAL '1' HOUR)
    GROUP BY window_start, window_end;
END;
Confluent Cloud makes this easier; see the documentation for details.
In some (rather unusual) cases it makes sense to avoid this issue entirely by using a query that doesn’t rely on watermarks. I’ll show a concrete example of this in Deduplicating Streams with Flink SQL, where ordering by a non-time column sidesteps watermarks entirely.
How much do I care about reducing latency?
There are cases where different solutions can have significantly different costs, in terms of the processing latency.
Many factors can introduce latency; here are some of the most significant:
- the checkpoint interval (only relevant for exactly-once semantics)
- the watermark delay (only relevant when watermarks are needed)
- timeframes built into a query, e.g., window duration
In my experience, paying attention to these straightforward points will be enough to meet the needs of most use cases. For those rare cases where very low latency is a must (e.g., sub-second end-to-end latency), much more careful tuning will likely be required.
Is this query deterministic?
Deterministic queries are easier to understand, easier to test, and much less likely to require painful debugging.
Some causes of non-determinism include:
Processing time. Relying on wall clock time, rather than event timestamps, leads to race conditions and inconsistent results.
Watermarks. Whenever watermarks are used, there can be late events that get dropped. Aggressive watermarking, to reduce latency, will make things worse.
Idleness. In cases where a source is expected to be intermittently idle, idleness detection is typically used to prevent the job from stalling indefinitely. However, when such a stream resumes, there’s a risk that the watermark will have already progressed past the timestamps in this stream, possibly rendering some or all of these events late.
State TTL. There’s a risk that the state needed to produce correct results will have been cleared by state TTL.
- Sources that behave non-deterministically when rewound/replayed. E.g., rehydrating query state from a Kafka topic with a finite retention period, or doing a lookup join against a REST API that returns different results when called again with the same input.
- Non-deterministic functions. E.g.,
now(),uuid(), andrand().
For more on this, see Determinism In Continuous Queries in the documentation.
Conclusion
The long-term vision for Flink is to improve usability by reducing the need for users to concern themselves with the details of how the runtime works. For example, the work on disaggregated state is intended to make it unnecessary to worry about unbounded state, while also making it practical to have more frequent checkpoints, thereby reducing the impact of checkpointing on end-to-end latency.
This post has primarily concerned itself with how to make good choices when writing Flink SQL queries, but there’s a lot more to think about as you operationalize your solutions. For best practice advice regarding configuration, deployment, security, etc., on Confluent Cloud, see Move SQL Statements to Production in Confluent Cloud for Apache Flink.
I’ll put this framework to work in Deduplicating Streams with Flink SQL, applying each of these considerations to a specific use case: deduplicating a stream of orders.